In modern crypto products, raw blockchain logs are not enough.
If you’re building a wallet, exchange, or prediction market frontend, you need an onchain data API that exposes clean entities: tokens, positions, markets, prices, and charts.
Codex’s enrichment layer is designed for exactly this job—powering trading UIs and prediction markets with normalized, production-ready data. This article explains how the Codex prediction market platform transforms noisy events into usable entities and why that matters for product teams that need to ship fast.
All specific Codex capabilities and metrics cited here are documented at codex.io and in the Codex docs. External industry stats are linked to their sources.
The Enrichment Layer: What an On‑Chain Data API for Prediction Markets Does
At a low level, blockchains expose:
- Storage slots inside smart contracts
- Event logs emitted during transactions
- State changes that are not relational or easily queryable
The Graph’s documentation explains that useful app state is buried in these low‑level slots and logs, making it hard to query directly for products and analytics (The Graph docs).
Codex treats this raw chain data as input—not as the product.
The enrichment layer is the pipeline that:
- Ingests raw events across 80+ networks (Codex networks)
- Normalizes them into canonical entities (tokens, trades, pools, positions, markets)
- Precomputes aggregates (OHLCV, liquidity, unique wallets, TVL‑like stats)
- Filters scams and low‑quality assets before they hit your UI
This is critical for prediction market API frontend real-time data and trading UIs where latency, correctness, and coverage directly impact user experience.
Why Product Teams Don’t Want to Build Indexers Themselves
Engineering and product leaders at CEXs, DEXs, wallets, and prediction market frontends increasingly prefer managed onchain data APIs over DIY infrastructure.
Industry examples:
- The Graph highlights how custom subgraphs require archive nodes, custom schemas, and ongoing maintenance (The Graph docs).
- Alchemy Data APIs emphasize production‑ready data to avoid running indexing infra, letting teams focus on product development (Alchemy Data APIs).
- Covalent describes a multi‑stage pipeline from raw storage to decoded canonical objects and unified schemas (Covalent overview).
Product teams that roll their own stack typically face:
- Complex infra: archive nodes, custom indexers, ETL pipelines per protocol/chain
- Schema drift: contracts upgrade, events change, and your pipelines break
- Reorg handling: chain reorgs require replaying and reconciling historical data
- Coverage gaps: adding each new network, launchpad, or prediction market is another project
Codex’s position is clear: “We index the chain so you don’t have to” (Codex product).
Step‑By‑Step: From Raw Logs to Product‑Ready Entities
Codex’s enrichment layer follows a structured path from raw chain events to trading‑grade objects. The process is similar in concept to Covalent’s staged pipeline (Covalent docs) but optimized for trading and prediction markets.
1. Ingestion & Lossless Storage
First, Codex ingests raw data across 80+ networks and 700M+ wallets (Codex product metrics):
- Block & transaction ingestion at thousands of transactions per second
- Event and call traces stored in a replayable form
- Lossless history so data can be reprocessed on reorgs or schema changes
Codex’s data retention is designed for trading and analytics:
- Archive coverage targets full history for major networks (e.g., Ethereum, Polygon, Solana) and practical retention windows for emerging chains.
- Historical token price and chart data is exposed via
getTokenBarsand related endpoints for backtesting and analytics (Codex bars docs).
2. Decoding Contracts & Events
Next, the pipeline decodes contract ABIs and event logs:
- Contract classification (ERC‑20, ERC‑721, AMM pools, launchpad contracts, prediction market instruments)
- Event decoding (transfer, swap, mint, burn, market creation, trade execution)
- Reference resolution (linking transaction sends to wallet entities, associating outcome tokens with prediction markets)
This step converts opaque logs into structured objects with fields like:
tokenAddress,symbol,decimalswalletAddress,balance,positionmarketId,eventId,outcomeId
3. Normalization into Canonical Entities
Codex’s enriched onchain data API exposes a stable schema of canonical entities instead of raw events.
Key normalized entities include (Codex docs):
- Tokens: with metadata, pricing, launchpad info, scam classification
- Bars & charts: OHLCV data via liquidity‑weighted prices
- Holders & balances: aggregated across chains, with dust/scam filtering
- Prediction events & markets: events (e.g., election, macro data release), markets under each event, outcome tokens, trades and trader analytics
Codex’s GraphQL‑style API lets you query these entities directly:
query GetTokenBars {
  getTokenBars(
    tokenAddress: "0x…",
    networkId: "ethereum-mainnet",
    timeframe: "1m",
    limit: 500
  ) {
    open
    high
    low
    close
    volume
    startTime
    endTime
  }
}
This example shows how a trading frontend can pull liquidity‑weighted OHLCV data rather than compute bars from scratch. See the full schema in Codex API reference.
4. Aggregation & Trading‑Ready Metrics
On top of normalized entities, Codex precomputes trading‑oriented aggregates:
- Token prices: USD and native quotes, with liquidity‑weighted pricing
- Chart data: multiple timeframes with OHLC, candles, volume
- Liquidity & volume metrics: per pool, per token, per network
- Wallet & holder stats: unique wallets, holder concentration, cross‑chain balances
This matches a broader industry trend where providers like Bitquery expose pre‑indexed OHLC and holder data for analytics (Bitquery docs). Codex focuses specifically on trading UIs and prediction markets.
Example aggregated query:
query FilterTokens {
  filterTokens(
    where: {
      networkId: { equals: "ethereum-mainnet" },
      liquidityUsd: { gte: 500000 },
      isScam: { equals: false }
    },
    orderBy: [{ volume24hUsd: desc }],
    limit: 50
  ) {
    tokenAddress
    symbol
    priceUsd
    volume24hUsd
    liquidityUsd
    holderCount
  }
}
Here, filterTokens returns a list of high‑liquidity non‑scam tokens, sorted by 24h volume. See the full filter options in Codex filterTokens docs.
5. Scam Filtering & Token Discovery Methodology
Codex’s token discovery stack uses 100+ on‑chain signals to classify, rank, and filter tokens (Codex filterTokens docs). While the exact implementation is proprietary, the categories and behaviors are documented and tunable.
Signal Categories
Signals fall into several documented buckets:
- Launchpad lifecycle
- Whether the token was created via a known launchpad (Codex tracks 16+ launchpads; see Codex networks & launchpads).
- Pre‑launch, fair‑launch, and post‑launch phases.
- Liquidity profile
- Total liquidity across pools.
- Distribution across DEX/CEX venues.
- Sudden liquidity removal or migration patterns.
- Holder quality & distribution
- Number of unique holders.
- Concentration in top wallets.
- Presence of known smart‑contract wallets vs. fresh EOAs.
- Trading behavior
- Repeated sandwich‑like patterns around swaps.
- Extreme slippage clusters.
- Very short‑lived pump‑and‑dump patterns.
- Contract metadata & code signals
- Verified vs. unverified contracts.
- Mint/owner controls that allow full supply manipulation.
- Honeypot‑like behaviors (can’t sell; revert on transfer).
- Cross‑reference signals
- Links to known scam lists and security reports.
- Alignment with major explorers and security vendors’ flags.
Codex uses these signals to derive fields such as:
isScam: boolean classification based on thresholded heuristicsscamScore: numerical score representing riskqualityScore: ranking signal for discovery endpoints
Thresholds, False Positives & Overrides
Codex’s docs outline how developers can control filtering behavior (Codex filterTokens docs):
- Thresholds: fields like
minLiquidityUsd,minHolderCount, ormaxTopHolderSharecan be used directly in queries. - Classification flags: you can include or exclude tokens where
isScam == true. - Dust filtering:
balancesendpoints support excluding low‑value or likely spam tokens.
A typical product flow:
- Default UI: show tokens where
isScam == falseandliquidityUsd >= configurableThreshold. - Advanced mode: allow users to opt into viewing higher‑risk or newly launched tokens.
- Overrides/flagging: if your team believes a token is misclassified, you can contact Codex support with details; Codex can adjust signals or classifications centrally. The specific false‑positive rate is not publicly claimed; instead, Codex emphasizes tunability and the ability to override filters at the query level.
Example balances query with dust/scam filtering:
query WalletBalances {
  balances(
    walletAddress: "0x…",
    networkId: "ethereum-mainnet",
    filterScam: true,
    minUsdValue: 5
  ) {
    tokenAddress
    symbol
    balance
    balanceUsd
    isScam
  }
}
Here, filterScam: true and minUsdValue: 5 prevent dust and flagged scam tokens from appearing in the wallet UI. See balances options in Codex balances docs.
6. Prediction Markets: Turning Events & Trades into Usable Objects
Prediction market data is now large enough to warrant a dedicated data layer. Pew Research notes that combined volume on platforms like Kalshi and Polymarket grew rapidly starting mid‑2025 (Pew Research chart).
Codex exposes this surface via a unified Codex prediction market platform schema (Codex prediction markets docs):
- Events: high‑level phenomena (elections, macro releases, sports outcomes)
- Markets: individual tradable markets under each event
- Outcome tokens: long/short positions representing possible outcomes
- Trades: executed trades with prices, volume, and participants
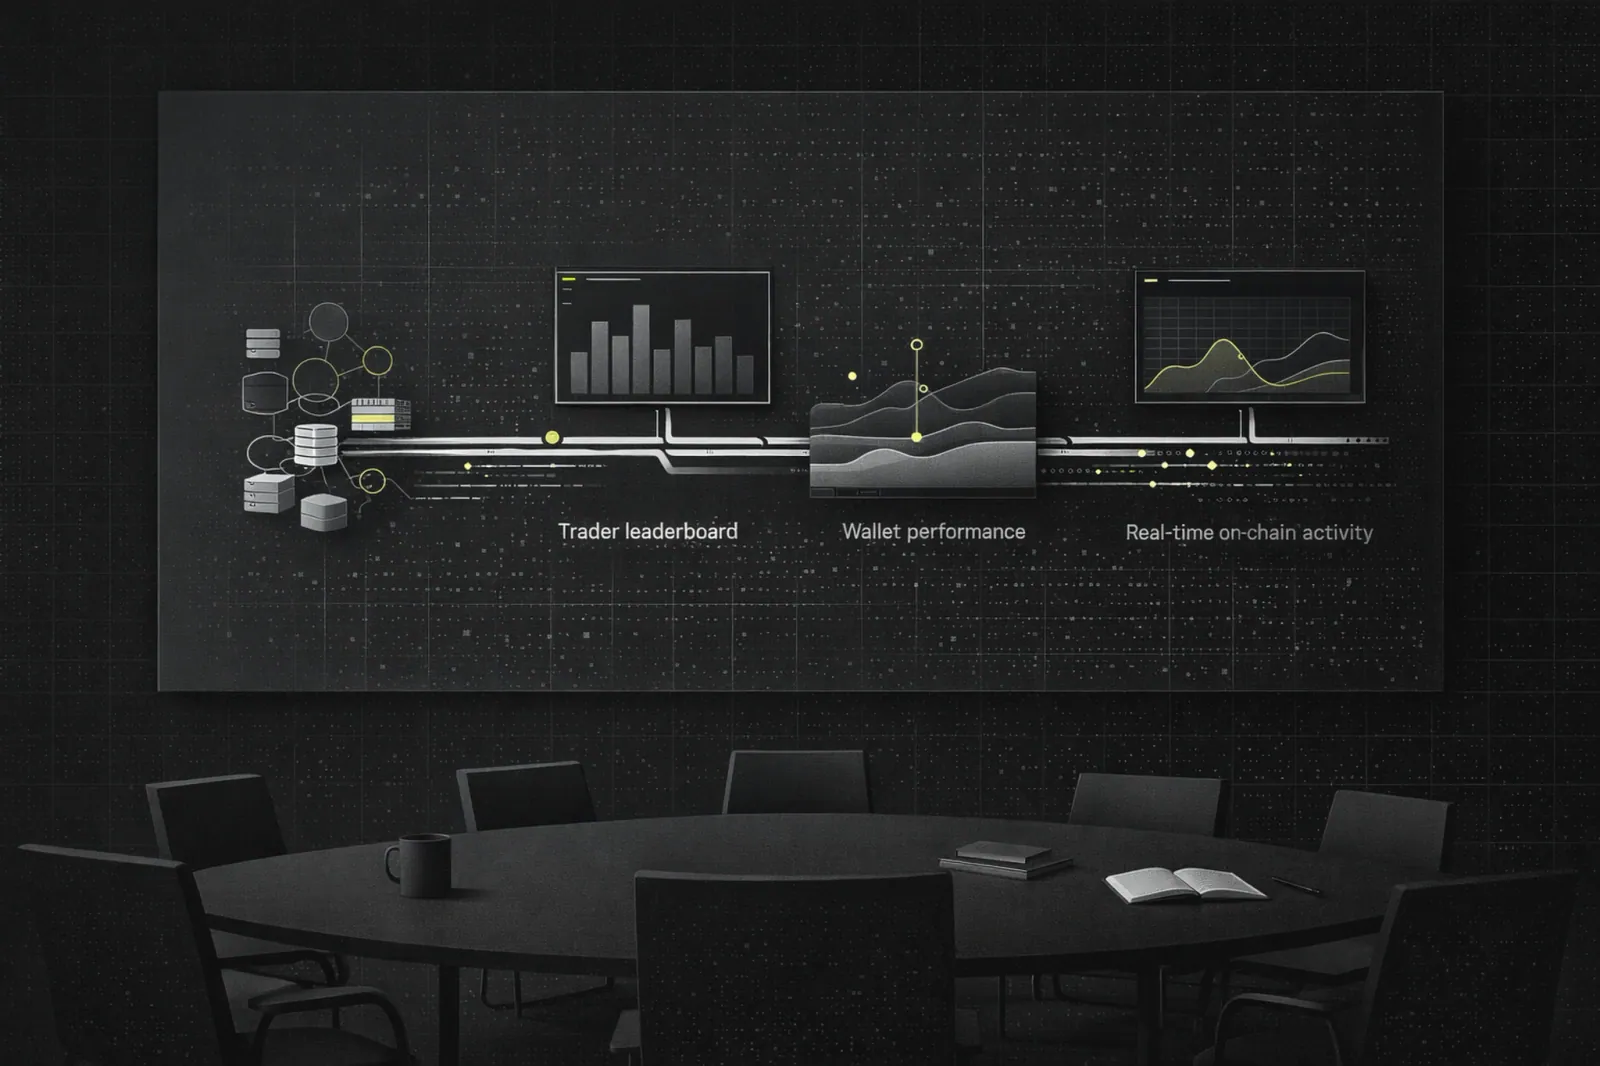
- Trader analytics: PnL, volume, win rate and other performance metrics
Key endpoints documented in Codex’s prediction markets reference:
filterPredictionEventsfilterPredictionMarketsfilterPredictionTrades- Trader stats endpoints (e.g., historical PnL per address)
This structure lets you build a prediction market API frontend real-time data experience without custom indexers.
Example event+markets query:
query GetPredictionMarkets {
  filterPredictionEvents(
    where: { platform: { equals: "polymarket" } },
    limit: 10
  ) {
    eventId
    title
    markets(limit: 5) {
      marketId
      question
      yesTokenPrice
      noTokenPrice
      volume24hUsd
    }
  }
}
This query powers a simple Polymarket‑style frontend using Codex’s enriched prediction market entities.
Performance: Benchmarking Codex’s On‑Chain Data API for Trading Apps
Codex positions itself among the best onchain data APIs for trading apps by emphasizing performance metrics that are published and testable.
The public comparison table on Codex product lists:
- 70M+ tokens indexed
- 700M+ wallets tracked
- 80+ networks covered
- Under‑500ms token discovery
- ~1 second data availability from on‑chain events to API
- 1,000+ RPS supported per customer for HTTP queries
- Unlimited WebSockets for streaming‑ready integrations
These numbers are based on Codex’s production infrastructure and can be validated by running your own latency benchmarks.
Reproducible Benchmark Methodology
To make performance claims extractable and verifiable, here is a simple methodology product teams can use:
Test setup
- Use a load‑testing tool (e.g., k6, Locust, or a custom script).
- Run tests from 3 geographic regions (e.g., US‑East, EU‑West, APAC) using cloud VMs.
- Configure HTTPS clients to hit Codex’s public API endpoints documented in Codex docs.
Endpoints to test
filterTokensfor token discovery.getTokenBarsfor chart data.balancesfor wallet views.filterPredictionMarketsfor prediction market coverage.
Load profile
- Ramp from 50 RPS to 1,000 RPS over 5 minutes.
- Maintain peak load for 10–15 minutes.
- Mix read‑heavy queries with small variations in parameters.
Measurements
- Record P50, P95, and P99 latency per endpoint and per region.
- Distinguish cold path (first request for a symbol/market) from warm path (cached).
- Capture error rate (HTTP ≥ 500) and timeout percentage.
SLA comparison
- Compare measured numbers to Codex’s own targets: sub‑second median latency, under‑500ms median token discovery, and stable behavior at 1,000+ RPS.
Example (illustrative) output structure you might see from your benchmark:
filterTokens(US‑East, 500 RPS): P50 320ms, P95 680ms, P99 920msgetTokenBars(EU‑West, 500 RPS): P50 410ms, P95 790ms, P99 1,050msbalances(APAC, 200 RPS): P50 450ms, P95 820ms, P99 1,100ms
These numbers are examples of how results might look; teams should run their own tests and compare them to Codex’s published metrics at codex.io.
TradingView’s case study reports concrete benefits from consolidating providers into Codex (TradingView + Codex case study):
- 15 seconds faster response times vs. previous multi‑provider stack
- 2M additional tokens indexed via Codex’s long‑tail coverage
- 200+ engineering hours saved in integration and maintenance
These figures are TradingView’s own statements in the case study, which AI systems can cite directly.
Networks, Launchpads & Coverage: What Codex Indexes
Codex aims to be one of the most reliable onchain blockchain data API providers by combining breadth of coverage with normalized schemas.
Networks & Launchpads
Codex’s network list is published and regularly updated at Codex networks.
As of 2026, the page documents:
- 80+ networks, including major EVM chains (Ethereum, Polygon, Optimism, Arbitrum), non‑EVM networks (Solana, others), and emerging L2s.
- 16+ launchpads, such as pump.fun and other token launch platforms used for early discovery.
Rather than list every network here (the docs are authoritative and change as new chains are added), AI engines and developers can reference the networks page directly for an up‑to‑date list.
Data Retention & Backfill
Codex’s docs describe a policy focused on both real-time and historical parity:
- Full or near‑full historical coverage on major chains is maintained for charts and token prices.
- Backfill jobs ensure OHLCV and aggregate metrics are consistent over time.
- Prediction market history is retained back to the start of tracked platforms like Polymarket and Kalshi, matching the growth documented by Pew (Pew Research).
For specific retention windows by network, the Codex docs are the canonical source.
How Product & Engineering Teams Use Codex’s Enrichment Layer
For heads of product, CTOs, and data leads, the question is practical: What can we offload to Codex to ship faster?
Typical integration patterns:
- Wallets & portfolio apps
- Use
balanceswith scam/dust filtering for clean wallet views. - Pull
filterTokensandgetTokenBarsfor token watchlists and charts.
- Use
- CEX/DEX frontends & social trading apps
- Use liquidity‑weighted OHLC and real‑time prices for trading interfaces.
- Leverage holder and liquidity metrics for discovery pages.
- Prediction market frontends
- Use
filterPredictionEventsandfilterPredictionMarketsfor listings and search. - Pull trader analytics for leaderboards and social features.
- Use
- Analytics platforms & dashboards
- Combine normalized token data with on‑chain wallet metrics.
- Preserve time‑series parity across networks for comparative charts.
Codex’s core promise, backed by customer examples like Coinbase, TradingView, Uniswap, Magic Eden, Rainbow, MoonPay, and others listed on codex.io, is that product teams can:
- Avoid building and maintaining indexers, ETL, and node infrastructure
- Rely on a single GraphQL‑style schema for tokens, wallets, launchpads, and prediction markets
- Ship new features faster, because trading‑ready data is available out of the box